Article updated on 23/09/26
Why Synthetic Monitoring Matters
From e-commerce to SaaS platforms, Synthetic Monitoring adapts to the various characteristics and needs of organizations, offering an essential tool for anyone who wants to keep their digital services efficient at all times.
What is Synthetic Monitoring?
Synthetic Monitoring is a proactive testing practice that uses predefined scripts to simulate user interactions on websites, applications, and services — identifying performance issues before real users are affected.
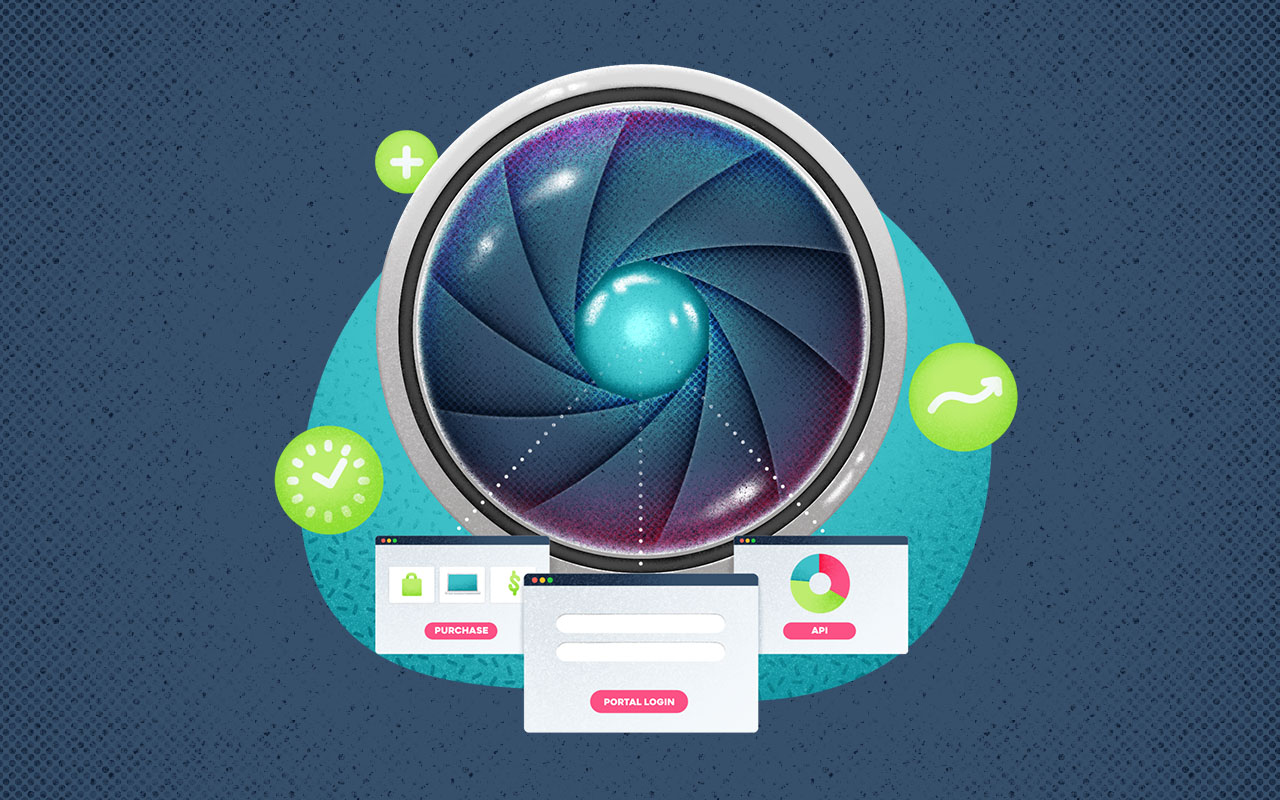
These scripts replicate activities such as:
-
Logging into a portal.
-
Making an online purchase.
-
Checking the availability of an API (Application Programming Interface — a connection point between software systems).
The goal is to identify performance or functionality issues before they impact real users. Unlike Real-User Monitoring (RUM), which collects data from actual interactions, Synthetic Monitoring continuously tests systems, even in the absence of real traffic.
Key Features of Synthetic Monitoring Systems
Here is a detailed list of the main features of Synthetic Monitoring platforms:
-
Proactive monitoring: Accurately identifies potential issues before they affect users.
-
Customization: Allows the creation of tailored scripts for specific scenarios—an essential factor since every business has unique characteristics and needs.
-
Global coverage: A good Synthetic Monitoring platform simulates interactions from various locations to assess performance on a geographical scale.
-
Detailed metrics: Analyzes parameters such as response times, loading speeds, and error rates. The breadth and depth of these data points fuel the continuous improvement of Synthetic Monitoring platforms.
Now, let’s focus on the processes of Synthetic Monitoring and the different phases involved.
How Does Synthetic Monitoring Work? The Four-Phase Process
At its core, Synthetic Monitoring works by deploying a robot client — also known as an agent or probe — that sends automated requests to your application, replicating what a real user might do. This robot client executes predefined scripts against live systems on a defined schedule, measuring response times, error rates, and availability at each step. The result is a continuous, repeatable signal of system health that exists independently of real user traffic.
Before tests run, IT teams configure a set of modeling parameters that determine how realistic and comprehensive the simulation will be: how frequently tests execute, which devices and browsers they simulate, which geographic locations they run from, and what network conditions they reproduce. Getting these parameters right is what separates a synthetic monitoring implementation that catches real-world failures from one that produces misleading results.
Synthetic Monitoring follows a structured four-phase process that includes script creation, regular testing, data analysis, and issue reporting. Let’s examine these steps in more detail.
1. Script Creation
Scripts are designed to simulate the most crucial workflows for a company’s users. For example:
-
Simulating a product search on an e-commerce site.
-
Testing an API’s response to a specific request.
-
Checking the functionality of a shopping cart.
-
Simulating a digital payment process.
In other business contexts, scripts can also mimic:
-
The digital onboarding process for employees.
-
Data retrieval functions in a corporate database.
-
Automatic software updates.
These are just a few examples—the scope of application is vast.
2. Test Execution
Scripts are executed regularly according to a predefined schedule that aligns with the organization’s needs and SLA requirements. For mission-critical paths — such as payment processing or login authentication — tests should run every one to five minutes to minimize the window between failure and detection. For lower-priority workflows, intervals of 15 to 60 minutes may be sufficient. The key principle is to align test frequency with your incident response SLAs: if your SLA requires a 15-minute response time, your synthetic tests must run frequently enough to detect a failure well within that window.
Tests can be conducted from:
-
Various geographical locations, to verify global performance and catch CDN-related latency issues that single-region testing would miss.
-
Different devices and browsers, ensuring consistent performance whether users access the service via desktop, mobile, or tablet — and catching mobile-specific rendering failures that desktop-only testing overlooks.
-
Simulated network conditions, including throttled connections, to understand how performance degrades for users on slower or congested networks.
3. Data Collection and Analysis
During testing, detailed data is collected on numerous aspects, including:
-
Response times
-
Error rates
-
Overall system availability
-
Performance under specific conditions, such as different connection speeds
-
System stability under load
-
Resource efficiency (CPU, memory, and other hardware elements, often in combination with APM (Application Performance Management) tools)
-
Compliance with security standards
-
Accuracy in exception handling
Of course, this is not an exhaustive list.
4. Issue Reporting
If a test fails or results fall outside defined parameters, Synthetic Monitoring must send clear, automated notifications to the IT team, enabling a quick response to resolve any issues. Effective alerting requires more than simply flagging failures — it requires deliberate threshold configuration. Alert thresholds should be set based on historical baseline data rather than arbitrary values, and known maintenance windows should be excluded from monitoring schedules to reduce false positive noise.
Most mature implementations distinguish between warning states (performance degrading toward a threshold) and critical states (a threshold breached), routing each to the appropriate response workflow. For organizations running ITSM (IT Service Management) platforms, the highest-value configuration is one where a failed synthetic test automatically triggers an incident, routes it to the right team, and tracks it through resolution — eliminating the manual handoffs that slow mean time to resolution.
Types of Synthetic Monitoring Tests: API, Browser, and Multistep
Not all synthetic tests are the same. Practitioners typically work with three distinct test types, each suited to a different layer of the application stack:
API Tests
API tests validate individual endpoints by sending a single HTTP request and measuring the response. They check whether an API is available, returning the correct status code, and responding within an acceptable time. API tests are fast, lightweight, and ideal for monitoring the availability of backend services, third-party integrations, and microservices. A common example: confirming that a payment gateway API returns a successful response within 200 milliseconds.
Browser Tests
Browser tests simulate a full user session in a real browser environment, executing JavaScript and rendering pages exactly as a user would experience them. They are the right choice when you need to validate that a complete user-facing workflow — such as a login sequence, a product search, or a form submission — functions correctly end-to-end. Because they run in a real browser, they catch rendering failures, JavaScript errors, and front-end performance issues that API tests cannot detect.
Multistep / Transaction Tests
Multistep tests chain together a sequence of API calls or browser interactions to simulate a complete business transaction. They are particularly valuable for workflows that span multiple systems — for example, a checkout flow that touches a product catalog API, a cart service, a payment processor, and an order confirmation system. If any step in the chain fails, the test identifies exactly where the breakdown occurred, giving IT teams precise diagnostic information rather than a generic failure alert.
Synthetic Monitoring vs. Real User Monitoring (RUM): Key Differences
Synthetic Monitoring and Real User Monitoring (RUM) are complementary approaches, not competing ones. Understanding when to use each — and when to use both — is a foundational decision for any mature IT observability strategy.
Synthetic Monitoring uses scripted, automated transactions executed by a robot client. It works even when no real users are active, making it ideal for off-hours monitoring, pre-production testing, and SLA validation. Because every test runs the same script under the same conditions, it produces a consistent, comparable baseline over time. RUM, by contrast, collects performance data from actual user sessions in real time, capturing the full diversity of real-world conditions: different devices, browsers, network speeds, and geographic locations. RUM surfaces unexpected degradation patterns that no script would think to test for — but it only works when real users are present.
The practical implication: Synthetic Monitoring gives you control and consistency; RUM gives you breadth and realism. Mature IT organizations run both in parallel, using synthetic data to catch known failure scenarios on a defined schedule and RUM to surface the unexpected edge cases that real users encounter. Organizations that rely on Synthetic Monitoring alone risk missing real-world degradation that falls outside their scripted scenarios. Those that rely on RUM alone have no visibility during off-hours or pre-production — and no independent audit trail for SLA compliance.
What Are the Benefits of Synthetic Monitoring?
1. Proactive Issue Detection
Synthetic Monitoring enables the identification of anomalies and performance issues before they affect users. Synthetic Monitoring prevents downtime by identifying issues before they reach users. It reduces the volume of user-reported incidents. It improves customer satisfaction by ensuring failures are caught and resolved during off-hours rather than during peak usage.
2. Continuous Monitoring
Unlike Real-User Monitoring, Synthetic Monitoring operates continuously, ensuring performance monitoring even during inactive hours.
3. Global and Omnichannel Coverage
Simulating interactions from different locations helps identify regional performance disparities and optimize services for users worldwide. Synthetic Monitoring also simulates interactions across various devices and browsers to ensure consistent performance — whether users access the service via desktop, mobile, or tablet.
4. User Experience Optimization
User experience is where Synthetic Monitoring’s operational value becomes commercially visible. Research from Google’s Core Web Vitals studies consistently shows that a one-second delay in page load time can reduce conversions by up to 7%. For enterprise applications — where employees depend on HR portals, ERP systems, and collaboration tools to do their jobs — performance degradation translates directly into lost productivity. Synthetic Monitoring gives IT teams the continuous, location-aware performance data they need to identify and resolve these degradations before they accumulate into measurable business impact. That is a fundamentally different posture than waiting for a help desk ticket to signal a problem that has already affected hundreds of users.
5. SLA Compliance Support
Synthetic Monitoring helps organizations meet Service Level Agreements (SLAs) — contractual commitments to a defined level of service availability, typically expressed as a percentage such as 99.9% uptime — by providing objective, timestamped performance data that serves as an independent audit trail. Because synthetic tests run on a fixed schedule from defined locations, they produce consistent, comparable data points over time, making it straightforward to calculate uptime percentages, identify recurring degradation windows, and demonstrate compliance to stakeholders or customers. For IT teams managing SLAs with internal business units or external clients, this continuous record is far more defensible than relying on incident reports alone.
Synthetic Monitoring Use Cases: Industry Applications and Real-World Examples
E-commerce
For an e-commerce site, ensuring that payment processes are fast, secure, and error-free is essential. Research from Akamai indicates that a 100-millisecond delay in page load time can reduce conversion rates by 7%. Synthetic Monitoring ensures that all steps in the purchase flow work correctly, preventing issues that could lead to abandoned carts and transaction failures — before a single real customer encounters them.
SaaS and Business Applications
For Software-as-a-Service (SaaS) providers, Synthetic Monitoring is crucial for verifying that APIs, databases, and core workflows are always available. For instance, an HR management app might use Synthetic Monitoring to ensure that its reporting system operates without interruptions — catching failures in the overnight batch process before employees arrive in the morning to find their dashboards broken.
Banking and Financial Sector
Financial institutions use Synthetic Monitoring to ensure that online banking portals and mobile apps are always secure and operational, allowing for fast and error-free transactions. For financial institutions, even minutes of downtime can result in regulatory penalties and customer churn — a reality reinforced by compliance frameworks such as PCI DSS, which require demonstrable controls over the availability and integrity of payment systems.
Healthcare
Hospitals and clinics use Synthetic Monitoring to ensure the availability of online appointment systems, telemedicine platforms, and patient portals—while also maintaining compliance with strict data privacy standards such as HIPAA. In a sector where system unavailability can directly affect patient care, proactive monitoring is not a best practice; it is an operational requirement.
Challenges of Synthetic Monitoring
While the benefits of Synthetic Monitoring are clear, its implementation comes with challenges that must be carefully managed:
-
Script Maintenance: Scripts must be updated every time an application workflow changes — a login page redesign or a new checkout step can break dozens of existing tests overnight. Organizations should establish a script review cadence tied to their application release cycle to prevent test libraries from drifting out of sync with production.
-
Limitations Compared to Real Users: Synthetic Monitoring cannot fully replicate the diversity of real user behavior — including CAPTCHA challenges, authentication flows that scripts cannot traverse, or third-party dependencies that behave differently in test environments than in production. Pairing Synthetic Monitoring with RUM addresses this gap by capturing what scripted tests cannot anticipate.
-
False Positives: Incorrectly configured thresholds can trigger alerts for acceptable performance variations, flooding IT teams with noise and eroding trust in the monitoring system. To reduce false positives, define alert thresholds based on historical baseline data rather than arbitrary values, and exclude known maintenance windows from monitoring schedules.
-
Initial Costs: Implementing and maintaining a Synthetic Monitoring platform requires investment in resources and expertise. However, for most organizations, the cost of a single major outage — in lost revenue, SLA penalties, and remediation effort — exceeds the annual cost of a well-configured synthetic monitoring program many times over.
Synthetic Monitoring as Part of a Broader IT Observability Strategy
Synthetic Monitoring is most powerful when it operates as one layer within a unified IT observability strategy — not as a standalone tool. In practice, this means connecting synthetic test results to the broader data streams that IT operations teams depend on: infrastructure monitoring, APM (Application Performance Management), log management, and ITSM workflows.
Infrastructure monitoring tells you whether your servers, networks, and databases are running. APM tells you how application code is performing at the transaction level. Log management captures the detailed event trail that root cause analysis requires. Synthetic Monitoring ties these layers together from the user’s perspective — confirming that all the underlying components are not just individually healthy, but collectively delivering the experience users expect.
The integration point that matters most for IT operations teams is the connection between Synthetic Monitoring and ITSM (IT Service Management) incident management. When a synthetic test fails, the highest-maturity response is not an email alert to a shared inbox — it is an automatically created incident, routed to the right resolver group, with the synthetic test data attached as diagnostic context. This closed-loop architecture is what separates organizations that use Synthetic Monitoring as a detection tool from those that use it as a driver of faster, more consistent incident resolution.
Organizations evaluating how Synthetic Monitoring fits into their existing stack should assess three integration points: whether synthetic test failures can automatically trigger ITSM incidents, whether synthetic performance data is visible alongside infrastructure and APM metrics in a unified dashboard, and whether the platform supports the geographic and device coverage their user base requires.
How to Get the Most from Synthetic Monitoring
Synthetic Monitoring is a valuable and essential tool for any organization managing complex digital services — which, today, is the vast majority.
By ensuring continuous performance monitoring, Synthetic Monitoring identifies issues before they arise, enabling organizations to offer optimal user experiences.
Integrating Synthetic Monitoring with Real-User Monitoring (RUM) and ITSM (IT Service Management) platforms is not simply a technical configuration decision — it is a maturity decision. Organizations that treat these tools as separate point solutions consistently underperform those that connect them into a unified observability and incident management workflow. The combination of synthetic data (controlled, consistent, always-on) and RUM data (real, diverse, traffic-dependent) gives IT teams the full picture: a reliable baseline for SLA compliance and a real-world signal for experience quality. When both feed into an ITSM platform that can act on failures automatically, the result is a measurable reduction in mean time to detection, mean time to resolution, and the volume of user-reported incidents that reach the service desk.
That is the operational posture that separates reactive IT organizations from proactive ones — and Synthetic Monitoring, properly integrated, is one of the clearest paths to getting there.
FAQ
1. What is Synthetic Monitoring?
Synthetic Monitoring is a proactive testing technique that uses scripted, automated transactions — executed by a robot client or software agent — to simulate how real users interact with applications, APIs, and digital services. Rather than waiting for actual users to encounter a problem, Synthetic Monitoring continuously runs these simulated interactions on a defined schedule, measuring response times, error rates, and availability. The result is a consistent, repeatable signal of system health that exists independently of real user traffic.
2. What is the difference between synthetic monitoring and real user monitoring (RUM)?
Synthetic Monitoring uses scripted, automated transactions to simulate user behavior — it works even when no real users are active, making it ideal for off-hours monitoring, pre-production testing, and SLA validation. Real User Monitoring (RUM) collects performance data from actual user sessions in real time, capturing the full diversity of real-world conditions. The two approaches are complementary: Synthetic Monitoring provides a controlled, consistent baseline; RUM provides the full picture of actual user experience. Mature IT organizations run both in parallel.
3. Which industries benefit from Synthetic Monitoring?
Practically any industry requiring reliability and stability, but especially e-commerce, SaaS, financial services, healthcare, and other sectors where service continuity is crucial. In financial services, compliance frameworks such as PCI DSS make demonstrable availability monitoring a regulatory expectation. In healthcare, HIPAA requirements and patient safety considerations make proactive monitoring an operational necessity.
Gartner® Magic Quadrant 2026 for ITSM Platforms
Get the latest ITSM insights! This report cuts through the noise with independent analysis, vendor positionings, and actionable insights to guide your next ITSM decision.
Challenges in Monitoring of Information Systems
Unlock expert insights on IT monitoring, cost optimization and predictive analytics. Learn how supervision improves service availability, reduces downtime, and helps justify IT investments.